
Twenty-one of the thirty-eight sites I could fetch sent fewer words than this sentence contains. For Lovable SEO, and for sites built with Bolt and Replit, that is the first thing to check: an AI crawler can only quote the words it actually receives.
I kept reading that sites built with AI tools are invisible to ChatGPT, always as an assertion, never with a number attached. So I measured it: 50 live sites built with Lovable, Bolt and Replit, each fetched twice, once the way an AI crawler fetches and once the way your browser does. Every script and every raw result is linked at the end.
Most of the sites showed almost nothing
Of the 50, eight were dead, one blocks crawlers deliberately, and seven failed to load or render. Of the 32 that remained and had enough content to judge, 20 depend on JavaScript for their text. Eighteen of those send between 1 and 11 words while their rendered pages carry between 54 and 1,408.
32 sites with enough content to judge. Share of the page's text present in the HTML a crawler receives.
Twelve sites deliver under 2% of their text. Ten deliver effectively all of it. Very little sits in between.
The other 12 were fine. Their text arrived in the HTML, sometimes almost word for word what a visitor sees. This is not "AI builders produce broken sites". It is closer to a coin flip, decided by settings most founders never see.
The head tags are fine. The page is not.
This part surprised me.
| In the HTML that actually arrives | Sites, of the 38 I could fetch |
|---|---|
| Title tag | 37 |
| Meta description | 36 |
| Canonical tag | 22 |
| A heading (H1) | 15 |
| Empty <div id="root"> shell | 20 |
Nearly every site has a title and a meta description, because the builder writes them into the template. Fewer than half have a heading in the delivered HTML.
That combination is why this gets missed. Run one of these sites through a typical SEO checker and it passes: title present, description present, lengths fine. The checker reads the tags. The AI crawler needs the article, and the article is not there yet.
Why this happens
A page can be delivered in two ways.
The first sends a finished page. The words are in the file that arrives, and anything that reads text can read them.
The second sends an almost empty file plus a program. The visitor's browser runs the program, which builds the page in front of them. People see a normal site. That empty <div id="root"> in 20 of these sites is the spot where the program will put the content, once something runs it.
Finished page
The words are in the file that arrives. Anything that reads text can read them.
Shell plus a program
An almost empty file, plus code that builds the page inside the visitor's browser.
AI crawlers read the file. They do not run the code.
Google runs those programs, in a second pass that can trail the first. The AI crawlers do not. Vercel and MERJ measured crawler traffic across their network, 569 million GPTBot fetches and 370 million from Claude in a single month, and found that none of the major AI crawlers execute JavaScript. They read what arrives, take what is there, and move on. If what arrives is nine words, nine words is what they know about your company.
Here is one of the measured sites, loaded both ways.
One of the measured sites. The left is what an AI crawler receives; the right is what a visitor sees once the browser has run the code.
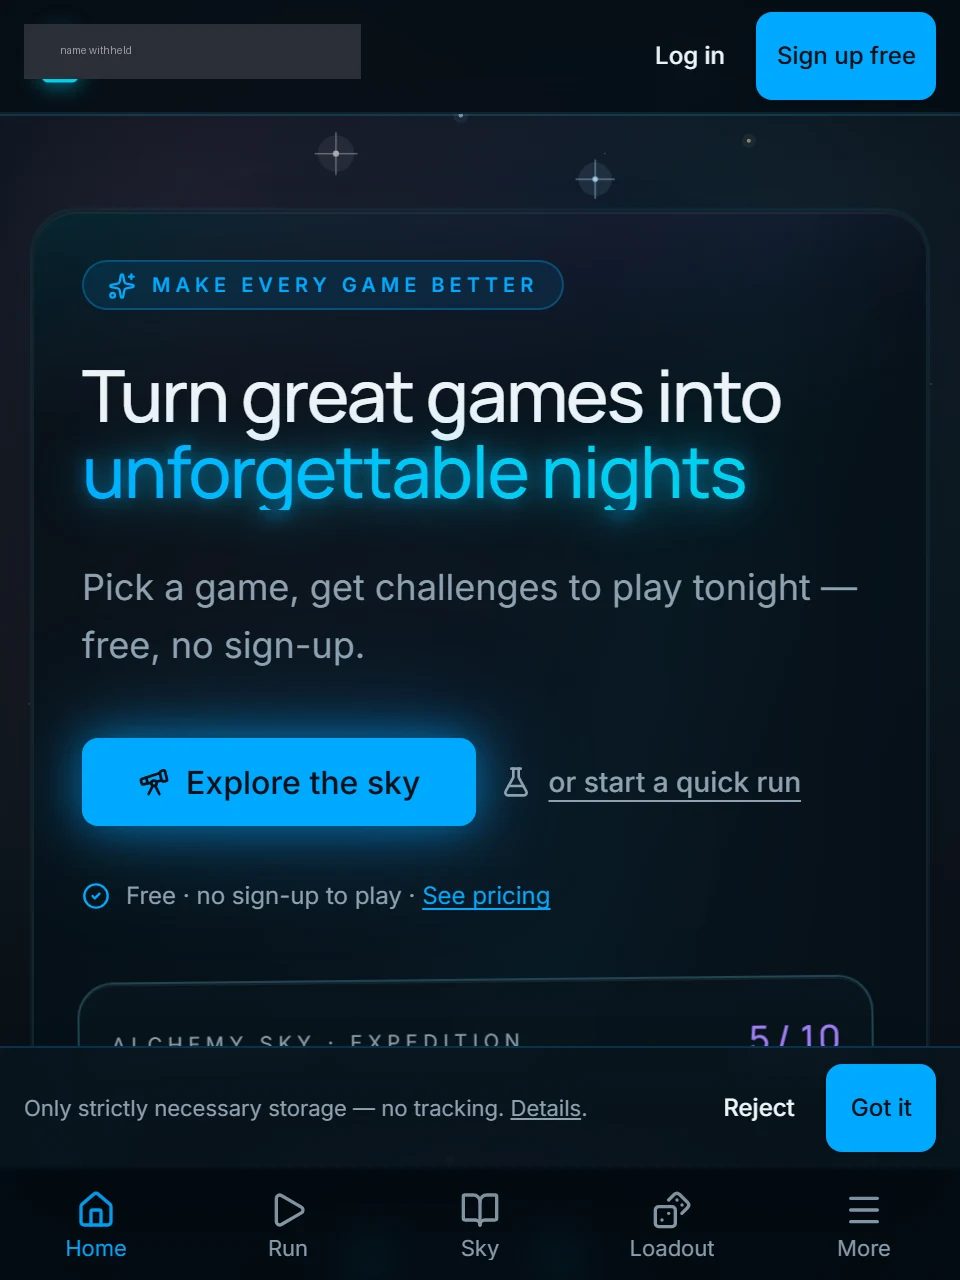
The site's name is covered. The point is the pattern, not one project.
How I picked the sites
I did not choose them. There are public directories of sites built with each tool: madewithlovable.com, madewithbolt.com and madewithreplit.com. For each one I read the outbound links in the order they appear in the page, removed infrastructure and social links, kept one entry per website, and took the first 20. Replit's directory lists fewer, so it contributed 13, and Bolt 17.
A side note worth having: eight of the 50 listed sites were dead when I checked, with their domains no longer resolving. That is what a directory of projects built quickly looks like a few months later.
How I measured them
For each site: read robots.txt first with a user agent that says who I am and links to this site, and obey it. Then one plain request with no JavaScript. Then one visit in a headless browser with JavaScript allowed. Then compare the words in each.
Under 50 words without JavaScript I called invisible. Under half the rendered text, partly visible. Otherwise readable. Sites with under 50 words even with JavaScript were set aside rather than counted.
What I checked before publishing this
The first version of this study had a bug in my own code. It reported 13 sites as "blocked by robots.txt" when they were simply unreachable. Two completely different claims, and only one of them was true. So every number here was re-derived with different tools than the ones that produced it:
- Text counted again with a real HTML parser instead of my regular expressions. It agreed on all 34 sites, and on the thin ones it found zero words where my first method found up to 11.
- Each page loaded again in a browser with JavaScript switched off, as an independent view. It matched on 33 of 34.
- Titles, descriptions and headings re-detected with the parser. No disagreements.
- Every site fetched twice. Same counts both times.
- The arithmetic recomputed from the raw rows: 34 measured, 8 dead, 1 blocked, 3 fetch failures, 4 render failures, totalling 50.
One site disagreed across methods. I chased it: it serves identical HTML to my fetcher and to Chrome, but hides the text with CSS until JavaScript reveals it. Which taught me something worth passing on: crawlers read what is present in the HTML, not what is visibly rendered. Hidden-but-present text still counts. Absent text does not.
By tool, with a warning
| Tool | Sampled | Could judge | Hidden or partly | Readable | Dead |
|---|---|---|---|---|---|
| Lovable | 20 | 19 | 9 | 10 | 0 |
| Bolt | 17 | 9 | 7 | 2 | 5 |
| Replit | 13 | 4 | 4 | 0 | 3 |
Do not read a ranking into this. Nine judged sites for Bolt and four for Replit are far too few to say one tool is worse than another. What the table does show is that the pattern appears in all three, not in one vendor's output.
The part that keeps me honest
Lovable's documentation says older React and Vite apps get on-request pre-rendering, "served only to verified search and AI crawlers". My fetcher is not on anyone's verified list. So for sites still hosted by Lovable, GPTBot may well receive more than I did. I could not check which sites are still on Lovable's hosting, because almost all of them answer from behind Cloudflare, which hides what is underneath.
So here is the claim I can defend, and the one I cannot.
I cannot tell you that ChatGPT specifically sees nothing on these sites. I can tell you that everything outside those verified allowlists sees nothing: link previews when someone shares you in a chat, smaller AI tools, research scrapers, and every AI product that launches next year without an entry on somebody's list. Your visibility then depends on a list you do not control.
Check your own site in 30 seconds
Open your site in Chrome, press F12, then Ctrl+Shift+P, type "Disable JavaScript", press Enter, and reload. What you see is close to what an AI crawler receives.
Or, in a terminal:
curl -s https://yoursite.com/ | sed -e 's/<[^>]*>/ /g' | tr -s ' \n' ' ' | wc -wUnder 50 words means there is nothing to read. Do it on an inner page too, not only the homepage. Product pages and articles are usually the ones you want quoted.
If your site fails
The fix is the same for every stack: send the finished page instead of assembling it in the browser. On Lovable that means upgrading the project to their server-rendered setup; their docs say apps created from 13 May 2026 already do this. Elsewhere, Next.js, Astro, Remix and SvelteKit all send finished pages by default, so the work is in moving, not in configuring something exotic.
And if you are about to pay someone to optimise your site for AI search, run the 30-second check first. On 20 of these sites, no amount of keyword work, schema markup or FAQ formatting would matter, because none of it is in the file that arrives.
The data
Everything is public: the sampling script, the measurement script, the cross-check, and the raw results for all 50 sites, in github.com/ram15126/ai-crawler-visibility-study.
The sites are anonymised in the charts above and named in the data, so any single row can be re-checked. The directories change over time, so a fresh run will sample a different 50. If you re-run it and get different numbers, open an issue: that is what the repository is for.
Frequently asked questions
Does this mean Google cannot see my site either?
Google is the exception. Googlebot runs JavaScript, in a second pass that can lag behind the first crawl. So a site can rank on Google and still be blank to AI assistants that only read the HTML your server sends.
Are Lovable, Bolt and Replit bad for SEO?
No, and this test cannot rank them against each other: after dead sites and failures I could judge 19 Lovable sites, 9 Bolt and 4 Replit. What the test shows is that the default output of these tools often depends on JavaScript, and that nobody warns the person shipping it.
How do I fix a site that fails this check?
Serve the finished HTML instead of assembling it in the browser. On Lovable that means upgrading to their server-rendered stack. Elsewhere, Next.js, Astro, Remix and SvelteKit all send finished pages by default.
Will adding a meta description help?
No. 36 of the 38 sites I could fetch already had one. What was missing was the page itself: only 15 had a heading in the HTML that arrived.
Is this the same as being blocked in robots.txt?
No, and the difference matters. One site in the sample disallows crawlers on purpose. The rest let crawlers in and then hand them a nearly empty file.